Open Source Alternatives
  • Alternatives
  • Categories
    Categories by size1,039 projects
    • Developer Tools530
    • AI & Machine Learning459
    • Business & Productivity241
    • Web Development204
    • Security & Monitoring155
    • Communication & Collaboration140
    • IT Management137
    • Cloud & Hosting122
    • LLMOps & AI Tooling120
    • Data & Analytics112
    Browse all 21 categoriesDesign & Creative, Product & Project Management and 9 more
  • Blog
  • Advertise
SearchNotion, Slack, password manager.../
Submit
Open Source Alternatives
  • Alternatives
    • Developer Tools530
    • AI & Machine Learning459
    • Business & Productivity241
    • Web Development204
    • Security & Monitoring155
    • Communication & Collaboration140
    • Browse all 21 categories
  • Blog
  • Advertise
Submit your project

New open source projects by email

The projects we add and every new guide. Free, unsubscribe any time.

Open Source Alternatives LogoOpen Source Alternatives

Handpicked Open Source Alternatives to Paid Softwares

Product

  • Categories
  • Tag
  • Advertise

Resources

  • Blog
  • Collection
  • Submit

Company

  • Privacy Policy
  • Terms of Service
  • Refund Policy
  • Sitemap

Alternatives

  • Claude Code
  • Jira
  • Notion
  • Slack
  • Linear
  • Wispr Flow
  • All alternatives
© 2026 Open Source Alternatives. All rights reserved.
Open SourceAlternatives
Home/Categories/AI & Machine Learning/LMCache
LMCache icon

LMCache

Open source alternative to Amazon SageMaker

  • 12.3K stars
  • Apache-2.0
  • Active this week
  • Last commit 2 days ago

Last verified Nov 1, 2026

Optimize LLM inference with a self-hosted KV cache layer that reuses context across vLLM deployments.

Visit websiteGitHub12.3K stars
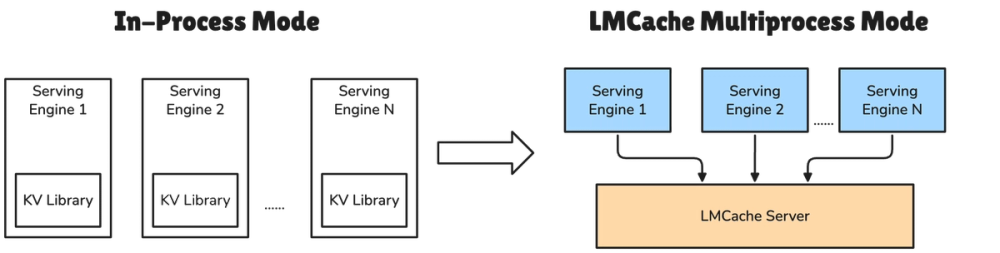
LMCache deployment modes diagram
TL;DR

LMCache is an open-source KDN that accelerates LLM applications by caching key-value pairs. It improves response times and reduces costs significantly. Ideal for AI chatbots and document processing tools.

Read the full breakdownHide the full breakdownWho it is for, how it works, trade-offs, the quick start and the FAQ
who it's for

Who LMCache is for#

Customer Support

Ideal for businesses looking to enhance AI-driven customer service applications.

Skip if:

If you do not require real-time interactions.

Document Processing

Streamline processing of large volumes of documents with fast retrieval capabilities.

Skip if:

If your application does not involve document handling.

the problem

The problem it solves#

LMCache addresses the slow response times and high costs associated with traditional LLM applications by implementing efficient caching mechanisms.

how LMCache solves it

How it solves it#

Prompt Caching

Enable fast, uninterrupted interactions with AI chatbots by caching long conversational histories.

Fast RAG

Enhance the speed and accuracy of RAG queries by dynamically combining stored KV caches.

Scalability

Effortlessly scales without complex GPU request routing.

Cost Efficiency

Reduces the cost of storing and delivering KV caches through novel compression techniques.

Cross-Platform Integration

Seamlessly integrates with popular LLM serving engines like vLLM and TGI.

strengths · trade-offs

Strengths and trade-offs#

Strengths

  • SpeedMinimizes latency with unique streaming and decompression methods.
  • QualityEnhances the quality of LLM inferences through offline content upgrades.

Trade-offs

  • -Complexity in SetupInitial setup may require technical expertise to integrate with existing systems.
versus alternatives

LMCache vs alternatives#

LMCache vs OpenAI Prompt Caching

LMCache and OpenAI Prompt Caching both reduce repeated LLM prefill work, but they serve different deployment models. LMCache is for teams running their own inference stack; OpenAI Prompt Caching is a managed API feature for teams already using OpenAI models.

FeatureLMCacheOpenAI Prompt Caching
LicenseApache-2.0Proprietary API feature
Self-hostingYes, runs with open inference stacks such as vLLMNo, handled inside OpenAI API infrastructure
Cache scopePersistent and tiered KV cache reuse across requests, sessions, engines, and storage backendsAutomatic prompt-prefix caching for eligible API requests
OperationsExposes KV cache observability, storage backends, and deployment controlsNo infrastructure to manage, but no control over cache placement

Choose LMCache when you operate self-hosted inference and need control over KV cache reuse, storage placement, observability, or multi-engine deployments. It is strongest for long-context agents, RAG, and repeated workloads where cache reuse can cut time to first token and improve throughput across your own serving fleet.

Choose OpenAI Prompt Caching when you want caching without owning inference infrastructure. It can reduce latency and input token cost automatically for repeated prompts, but it keeps the optimization inside OpenAI's managed API rather than your own deployment.

install · quick start

Quick start#

bash
Set up LMCache in the Python environment that runs your self-hosted inference stack.

```bash
pip install lmcache
lmcache --help
```
tech stack · detected from GitHub

What it's built on#

Languages
C++GoPythonRust
Frameworks
PyTorch
frequently asked

FAQ#

What is LMCache?

LMCache is an open-source Knowledge Delivery Network that accelerates LLM applications.

How does LMCache improve response times?

By caching key-value pairs, LMCache enables faster retrieval of information.

Is LMCache easy to integrate?

Yes, LMCache integrates seamlessly with popular LLM serving engines.

also worth a look

Similar open-source tools#

accelerate

Alternative toLightning AI

Distribute PyTorch training to multi-GPU and TPU with four lines

  • 9,935 GitHub stars
  • Apache-2.0Licence Apache-2.0

marin

Alternative toDatabricks

Open lab for training foundation models together

  • 4,053 GitHub stars
  • Apache-2.0Licence Apache-2.0

ODS

Alternative toChatGPT

Turn any computer into a private AI server

  • 7,730 GitHub stars
  • Apache-2.0Licence Apache-2.0

transformers

Alternative toGoogle Cloud Vertex AI

Model-definition framework for state-of-the-art ML

  • 168,420 GitHub stars
  • Apache-2.0Licence Apache-2.0

Ploomber

Alternative toGoogle Cloud Composer

Build reproducible Python data pipelines with DAG orchestration

  • 3,620 GitHub stars
  • Apache-2.0Licence Apache-2.0

Moxin-LLM

Alternative toOpenAI API

Full transparency LLM: open weights, training code, and data

  • 525 GitHub stars
  • Apache-2.0Licence Apache-2.0
by category

Open source tools in these categories#

459

AI & Machine Learning

freeCodeCamp, REA (Reverse Engineer Anything), OpenClaw
530

Developer Tools

REA (Reverse Engineer Anything), Skills for Real Engineers, superpowers
120

LLMOps & AI Tooling

Hermes Agent, OpenCode, MarkItDown
122

Cloud & Hosting

dify, RuView, rtk

Sponsors

Inbox Zero

Alternative toSuperhuman

AI email assistant that drafts replies and clears your inbox

  • 12,889 GitHub stars
  • AGPL-3.0Licence AGPL-3.0
  • #Email

rakazo

Alternative toGrok Bot

AI teammates you own: your keys, your model, your machine.

  • 6,568 GitHub stars
  • Apache-2.0Licence Apache-2.0
  • #AI Agents

SnitchFeed

Live monitoring on LinkedIn, X, Reddit & more. Agentic social listening for startups.

Marketing & Growth

Advertise your product

New open source projects by email

The projects we add and every new guide. Free, unsubscribe any time.

Find open source alternatives to paid software

/
  • Claude Code to OpenCode
  • Jira to Windshift
  • Notion to AppFlowy
  • Slack to Mattermost
  • Linear to GitLab
  • Wispr Flow to Handy
  • Arc to Zen Browser
  • CapCut to Concat
  • Grok Bot to rakazo
  • Superhuman to Inbox Zero
  • Airtable to AITable
  • Muse to OpenClaw
  • Railway to Coolify
  • GitHub Copilot to Cline
  • Datadog to Netdata
  • Microsoft Teams to Rocket.Chat
  • Confluence to Docmost
  • Pinecone to Qdrant
  • Zapier to n8n
  • Devin AI to OpenHands
  • Firebase to Supabase
  • 1Password to KeePassXC
  • Contentful to Strapi
  • Adobe Premiere Pro to Shotcut
  • Claude Code to OpenCode
  • Jira to Windshift
  • Notion to AppFlowy
  • Slack to Mattermost
  • Linear to GitLab
  • Wispr Flow to Handy
  • Arc to Zen Browser
  • CapCut to Concat
  • Grok Bot to rakazo
  • Superhuman to Inbox Zero
  • Airtable to AITable
  • Muse to OpenClaw
  • Railway to Coolify
  • GitHub Copilot to Cline
  • Datadog to Netdata
  • Microsoft Teams to Rocket.Chat
  • Confluence to Docmost
  • Pinecone to Qdrant
  • Zapier to n8n
  • Devin AI to OpenHands
  • Firebase to Supabase
  • 1Password to KeePassXC
  • Contentful to Strapi
  • Adobe Premiere Pro to Shotcut